URL 编码:查询串与特殊字符
对 URL 中的特殊字符进行百分号编码,或将百分号编码的 URL 解码为可读文本。
Which URL encoder mode do you need?
This is your one real decision, and that toggle above is all of it. encodeURIComponent is for one piece of a URL — one query value, one path segment, one token. It escapes every structural character, because inside one URL value those characters are text. encodeURI is for a whole URL, already assembled correctly and needing only its unsafe characters cleaned up, so it leaves URL structure alone.
Run https://example.com/search?q=hello world through both modes and your difference is obvious. encodeURI escapes only that space and leaves a working URL. Component mode escapes colon and both slashes as well, returning https%3A%2F%2Fexample.com%2F… — correct only when that entire URL is about to become one parameter inside another URL, such as an OAuth redirect target.
Rule of thumb: build your URL first, then encode each URL value as you put it in. If you find yourself running this URL encoder over text that already contains a ? you meant to keep, you want another mode.
What a URL encoder does to each character
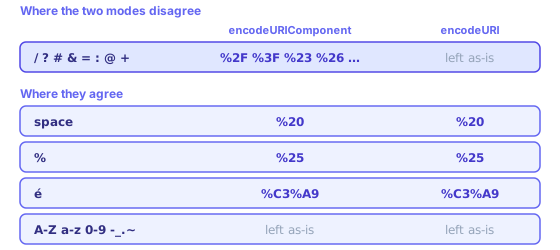
Percent-encoding replaces a character with % and its byte in hex. Both URL encoder modes agree on most of that alphabet, and disagree on exactly those characters which give the URL its structure:
- space → %20
- Most parsers end a URL at its first space, and mail clients stop linking there.
- & → %26 / &
- Unencoded, this starts a new query parameter — commonest way one URL value gets truncated.
- = → %3D / =
- Splits key from value, so an unencoded = inside the value confuses strict parsers.
- ? → %3F / ?
- Starts a query string. Two raw question marks in one URL are tolerated but never portable.
- # → %23 / #
- Starts a fragment, and fragments never reach your server. Everything after a raw # is lost.
- / → %2F / /
- Separates path segments, so an unencoded / inside the value invents another segment.
- + → %2B / +
- Form decoders read this as space, which is why plus signs vanish from email addresses in a URL.
- % → %25
- Escapes itself. Skip this and an already-encoded URL decodes into nonsense twice over.
- é, 中, 🎉 → %C3%A9 …
- Encoded as UTF-8 bytes, so one character becomes two, three or four triplets.
Letters, digits and - _ . ~ are unreserved and never change in either mode. JavaScript also leaves ! * ' ( ) alone, which is that language rather than RFC 3986 — strict encoders escape those too, so two URL encoders can both be right and still disagree.
Double encoding, and the plus-sign trap
If you see %2520 in a URL, something encoded it twice. One pass turned space into %20; a second read that % as an ordinary character and turned it into %25, leaving %25 + 20. It happens when your framework already encoded the value and some helper did it again. Decode once here; if your result still holds % sequences, decode again, then fix whichever layer is doubling up.
Plus signs are another classic. In query strings built by an HTML form — application/x-www-form-urlencoded — space is written as +, not %20. Percent-decoding does not know that rule: decode a+b here and you get a+b back, not a b. When reading form data, replace + with space before decoding. Going outward, one real plus inside the value must become %2B or it arrives as space — which is exactly why name+tag@example.com keeps losing its plus in signup forms.
One security note: URL decoding is not sanitising. Decoded URL text can contain anything, so validate it before it reaches your database, your filesystem or another URL. Percent-encoding hides ../ and script tags just as happily as it hides spaces.
Where URL encoding shows up in practice
Tracking links are your everyday case: every UTM parameter, every ?q= pasted out of a search box. OAuth redirect URIs are what people get wrong, because a whole callback URL becomes one parameter inside an authorise URL and must be component-encoded. API tokens need it whenever Base64 puts + or / inside them. Non-ASCII hosts use a different scheme entirely — punycode, so münchen.de becomes xn--mnchen-3ya.de, while the URL path after it percent-encodes normally.
One confusion worth naming: URL encoding is not HTML encoding. Percent-encoding makes text safe inside a URL; HTML entities make text safe inside markup. One ampersand becomes %26 in a URL and & in a page, so if & is turning up in your address bar, something ran the HTML encoder where this one belonged.
In code the same two modes keep the same names. JavaScript gives you encodeURIComponent(value) and encodeURI(url), with decodeURIComponent and decodeURI to reverse them. Python splits the same idea into urllib.parse.quote and quote_plus, and PHP into rawurlencode (space becomes %20) and urlencode (space becomes +) — the plus-sign trap again, baked into a standard library.
A URL encoder is not the same job as making the URL readable. If you want Café Münster to become cafe-munster rather than Caf%C3%A9%20M%C3%BCnster, that is the slug generator. And if a token you are decoding turns out to be Base64 rather than percent-encoded, the Base64 decoder is the one you want.
URL 编码:查询串与特殊字符
按 RFC 3986,空格与 ?#& 等字符在拼接 URL 时应先编码;解码还原 %XX 与 UTF-8 文本。
注意避免二次编码,必要时与框架自带方法对照。
Non-ASCII text came later and works in two steps: each character becomes UTF-8 bytes, then every byte becomes its own triplet. That is why an accented letter costs two triplets, a CJK character three and an emoji four — and why the same URL in any language but English looks so much longer than its readable form. Decode with the wrong charset assumption and you get mojibake rather than an error, which makes it a quiet bug.
None of this is compression or security. A percent-encoded URL holds the same information in longer form, readable by anyone, and any URL decoder reverses it in one pass. Percent-encoding exists so arbitrary text can travel inside a format that reserves a dozen characters for its own grammar — nothing more, and nothing to rely on for hiding a URL value.
Worked examples
encodeURIComponent("café & crème")
  → caf%C3%A9%20%26%20cr%C3%A8me

encodeURI("https://example.com/a b?q=café&x=1")
  → https://example.com/a%20b?q=caf%C3%A9&x=1
Component mode encodes &, =, ? and / so a value cannot break out of its place in the URL; full-URL mode leaves those structural characters alone and only encodes what is not allowed anywhere. When building a query string in code, encode each value with encodeURIComponent, or let URLSearchParams do it for you.
Decoding pitfalls
- A + in a query string from an HTML form means a space; decodeURIComponent leaves it as +, so replace + with a space first when decoding form data.
- A stray % that is not followed by two hex digits makes decoding fail — the text was probably never encoded, or was cut off.
- If a value still contains %XX after decoding, it was encoded twice; decode once more.
In-depth guides
- Base64 and URL Encoding: When to Use Which
Base64 is not encryption. Learn URL-safe variants, where padding matters, and how to avoid double-encoding form fields and API query strings.
Related tools
These free tools pair well with this page — open them in a new tab to finish your workflow.
常见问题
什么是URL编码?
URL编码(百分比编码)将URL中不允许的字符转换为安全格式。例如空格变为%20,&变为%26。
什么时候需要URL编码?
将文本嵌入URL查询字符串时需要编码,特别是包含空格、&、=、+或非ASCII字符时。
encodeURI和encodeURIComponent有什么区别?
encodeURI编码完整URL,保留/、?、&等字符不变;encodeURIComponent编码URL组件(如查询值),会转换这些字符。对单个参数值使用encodeURIComponent。
应该编码整个URL还是只编码部分?
编码单个查询参数值,而不是整个URL。编码整个URL会破坏其结构,因为斜杠和冒号也会被编码。
哪些字符不需要编码?
非保留字符——字母(A-Z, a-z)、数字(0-9)和-._~——不需要编码,直接传递。
解码所有编码字符串是否安全?
解码通常是安全的,但要注意不要将不受信任输入解码后直接用于URL或数据库查询,以免引入注入漏洞。