When to reach for an HTML encoder, and when the framework has it covered
特殊文字をHTMLエンティティに変換、またはHTMLエンティティをプレーンテキストにデコードします。
67
Input chars
118
Output chars
Common HTML entities
Decode HTML entities online
Switch to Decode → Text, paste something like <p>Tom & Jerry</p> and this HTML decoder gives back <p>Tom & Jerry</p>. It runs in your browser as you type, so nothing you paste is uploaded.
You will see this job called several things. HTML decode, HTML unescape and HTML entity decoder all mean turning entities back into the characters they stand for; people looking to decode HTML online usually have text copied from page source, an RSS feed, a JSON API response or a database column that was escaped once too often. Some call it an HTML deobfuscator when a page hides an email address or a snippet behind numeric entities such as mail — decoding reveals that text, but it does not unpack minified or obfuscated JavaScript.
What an HTML encoder actually protects you from
A browser cannot tell your markup apart from markup that arrived in a comment box. It parses whatever it is given. An HTML encoder is how you say “treat this as text”:
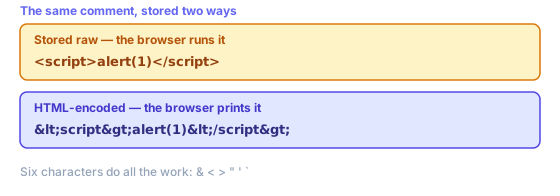
That is the whole mechanism behind escaping user content, and why an HTML encoder sits in the output path of almost every web framework. Six characters do all of it:
- <
- Opens tags. Left raw, comments containing <script> stop being text and become markup your browser runs.
- >
- Closes tags. Escaped mainly for symmetry, and because some parsers will happily repair half-broken tags for an attacker.
- &
- Starts every HTML entity, so it goes first. Escape it last and you re-escape ampersands you just created.
- "
- Ends double-quoted attribute values, letting anything after it become a new attribute — onerror, say.
- '
- Ends single-quoted attributes in exactly that way. Written numerically because ' is not in HTML 4 and older parsers ignore it.
- `
- Not special in HTML itself, but old versions of IE accepted backticks as attribute delimiters. Cheap to escape, so it is escaped.
Escaping is per context, not per value
This is what catches people out. Values are not “escaped” in general — they are escaped for somewhere. One string needs different treatment depending on where it lands, and the wrong scheme gives all the comfort of having escaped something with none of the protection:
- HTML body text
- What this HTML encoder is built for. Escape those six characters and user content renders as whatever someone typed.
- An attribute value
- Same HTML entities, but quote your attribute too. An unquoted attribute can be ended by a space, which no amount of escaping prevents.
- Inside a <script> block
- HTML entities do not help — JavaScript parsers never decode them. Serialise your value as JSON instead, or pass it through a data attribute and read it from the DOM.
- A URL or query string
- Percent-encoding, not HTML entities. Different alphabets solving different problems; neither substitutes for another.
- Inside a style block
- Neither scheme is enough. CSS has its own escape syntax and its own injection routes, so never build style rules out of user input.
If your destination is a link rather than a page, you want the URL encoder instead — ampersands are & in markup but %26 in URLs. Escape once, for the right destination, at the moment you write that value out.
Named, numeric and hex entities
Every character has three ways of being written as an HTML entity. An ampersand is & by name, & by decimal code point and & by hex. All three decode identically, and this HTML decoder accepts all three.
Named HTML entities read better, but only five are defined in XML: &, <, >, " and '. HTML defines well over a thousand more, which is why works in web pages and breaks RSS feeds. Numeric HTML entities are safe everywhere, so they are your right choice for XML, SVG and anything you cannot inspect.
Note that this HTML encoder writes ' rather than ' for an apostrophe, for exactly that reason — numeric HTML entities have always worked, and ' was not part of HTML 4.
Double encoding, and what this HTML decoder will not do
Seeing &lt; on a page means something escaped an already-escaped string. One pass turned < into <; a second read that ampersand as an ordinary character and turned it into &, so your reader gets literal text instead of a tag. Almost always some template escaped a value your framework had already escaped. Decode twice here to confirm, then remove one layer.
One honest limit: this HTML decoder handles numeric and hex entities in full, plus the couple of dozen named HTML entities you actually meet — , ©, — and friends. HTML defines far more, so rarer named entities such as ö pass through unchanged rather than becoming ö. If HTML entities survive a decode, that is why — and the numeric form of that character decodes correctly.
Decoding is also not a security step. An HTML encoder protects whatever page displays your value; decoding hands back original characters, tags and all. Never decode untrusted input and then insert that result into your page — it undoes the protection an HTML encoder just gave you.
When to reach for an HTML encoder, and when the framework has it covered
Most of the time you should not be calling an HTML encoder by hand at all. React, Vue, Svelte, Rails, Django and Laravel all escape interpolated values on their way out by default, which is why XSS stopped being routine in ordinary app code. Bugs now cluster at deliberate escape hatches — dangerouslySetInnerHTML, v-html, html_safe, |safe — where you told your framework to stop escaping HTML for you.
So the honest use for a standalone HTML encoder is everything outside that path: pasting a snippet into a blog post so its tags show as tags rather than rendering, putting markup inside an XML or RSS field, writing an email template by hand, or cleaning a legacy dump where someone stored HTML entities, someone else stored raw text, and nobody wrote down which column is which.
An HTML encoder is also the quickest way to see what a value will actually become. Escaping is hard to reason about from memory because each layer looks reasonable alone, and its failures — a doubled HTML entity, an unescaped attribute, an entity that survived decoding — are obvious once you see before and after side by side. Paste your string in, read the output, and the answer stops being a guess.
What no HTML encoder can do is decide where your value is going. It escapes for markup and nothing else, so values bound for script blocks, URLs or stylesheets need a different scheme entirely. Getting that call right is the actual skill; escaping HTML itself is a lookup table.
In-depth guides
- Base64 and URL Encoding: When to Use Which
Base64 is not encryption. Learn URL-safe variants, where padding matters, and how to avoid double-encoding form fields and API query strings.
Related tools
These free tools pair well with this page — open them in a new tab to finish your workflow.
よくある質問
HTMLエンコーディングとは何ですか?
HTMLエンコーディング(エスケープ)は、HTMLで特別な意味を持つ文字をエンティティに変換してリテラルテキストとして表示します。例:<は<に、>は>に、&は&に、"は"に変換されます。
HTMLエンコードはいつ必要ですか?
ユーザーが入力した信頼できないテキストをHTMLページに挿入する際は必ずエンコードが必要です。エンコードなしでは<や>がHTMLタグとして解釈され、クロスサイトスクリプティング(XSS)脆弱性が生じる可能性があります。
XSSとは何ですか?エンコーディングはどのように防止しますか?
XSS(クロスサイトスクリプティング)はWebページに悪意のあるコードを埋め込む攻撃です。ユーザーが<script>alert('xss')</script>と入力してそのまま表示すると、スクリプトが実行されます。エンコードすると<が<になり、スクリプトはテキストとして表示されます。
HTMLエンティティとUnicodeエスケープの違いは何ですか?
HTML名前付きエンティティ(&など)は人が読みやすくHTML仕様の一部です。Unicodeエスケープ(&など)は同じ文字を数値で表現します。どちらもブラウザで同じ結果になります。名前付きエンティティの方が読みやすく、数値形式はあらゆる文脈で使えます。
スペースはエンコードする必要がありますか?
通常のスペースはHTMLエンコードは不要です。ただし、改行を防ぐスペースが必要な場合は または としてエンコードします。HTML属性では、誤解を招く値の一部でない限り通常スペースをエンコードする必要はありません。